Menu
Should Your Product Use AI? A Practical Guide

Muhammad Saeed
Software Engineer
Jul 19, 2026
10 min read
A practical guide for founders choosing between AI, automation, and standard software, with questions about data, privacy, testing, cost, and human review.
Contents10 sections
AI can be useful in a product, but “add AI” is not a product requirement. Start with the user’s problem, the decision the software must support, and the cost of getting that decision wrong.
The pressure to adopt is real, and so is the gap behind it.
Stanford HAI’s 2026 AI Index (opens in a new tab) reports that organisational AI adoption rose to 88% of surveyed organisations in 2025. It also notes that AI agent use “remains early” across nearly every business function.
Deloitte’s 2026 State of AI in the Enterprise (opens in a new tab) surveyed 3,235 senior leaders across 24 countries. It found 74% of organisations hoping to grow revenue through AI, against 20% already doing so.
Adoption is close to universal. Realised value is not.
That gap is the reason to slow down for one conversation before committing. The question is not whether AI is capable. It is whether this feature, for this user, is a problem AI is the right shape for.
When AI Fits — and When It Doesn’t
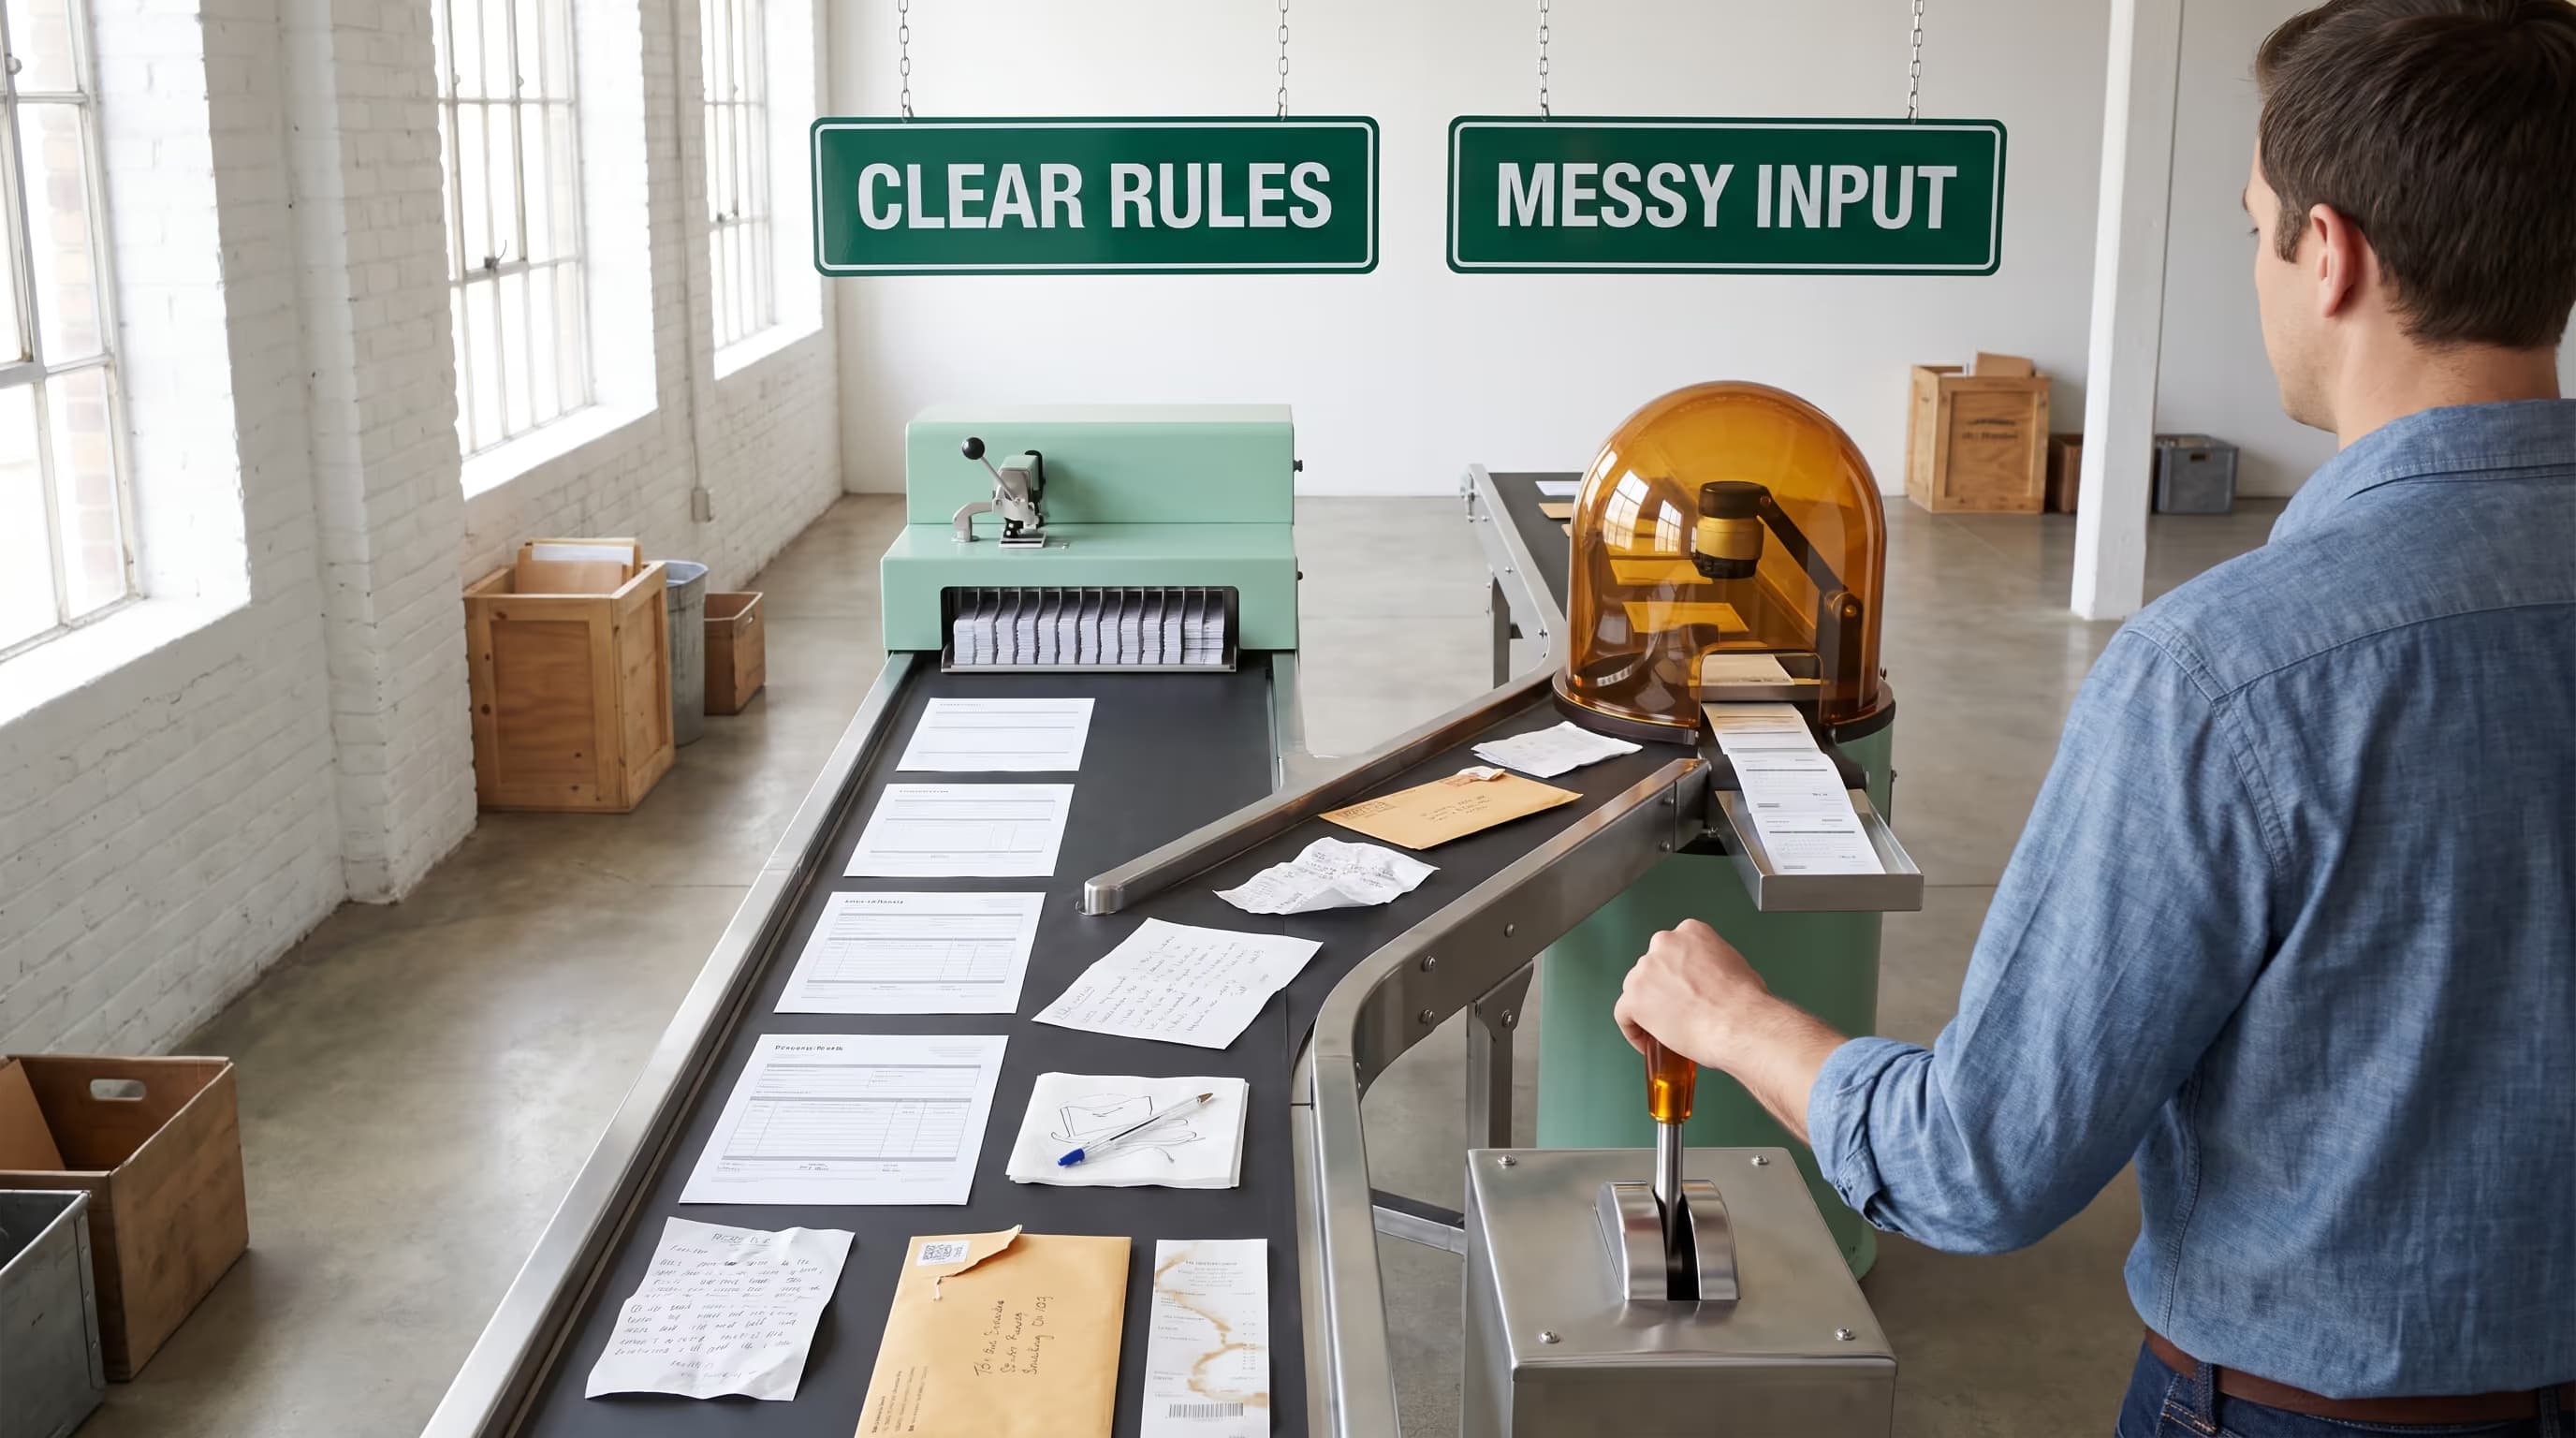
A normal workflow is often the better choice when the rules are clear. Forms, permissions, search, calculations, notifications, and scheduled tasks do not need a language model simply because one is available.
This is not a contrarian position. Google’s Rules of Machine Learning (opens in a new tab), its internal guidance for ML engineers, opens with a direct instruction: “Don’t be afraid to launch a product without machine learning.”
The reasoning is that a simple rule of thumb already captures much of the value. Machine learning earns its place once those rules get too tangled to maintain.
A conventional workflow is usually the better answer when:
- the rules can be written down and agreed by the people who own the process
- the same input should always produce the same output
- the cost of a wrong answer is high and the correct one is knowable in advance
- someone needs to explain precisely why the system did what it did
- the data is already structured, validated, and complete
AI earns its place when the input is messy, unpredictable, or hard to pin down with fixed rules:
- summarising long documents, threads, or call notes
- classifying free-text messages where phrasing varies widely
- extracting fields from documents that never follow one template
- helping a person explore information rather than deciding on their behalf
- drafting a first version that a human will review and edit
The pattern across the second list is that a human stays in the loop. The output is a draft, a suggestion, or a starting point rather than a final decision.
That is usually where these features earn their place first.
Start With the Right Question
The first question is not “Which model should we use?” Ask instead: “What should the user be able to do, and where does uncertainty enter the workflow?” That answer determines whether AI belongs in the product.
Decide what a good result looks like before you build. A draft summary may be fine with a quick human check. A decision the software makes on its own may need tighter controls, a clear explanation, and a safe way to stop or correct it.
NIST’s AI Risk Management Framework (opens in a new tab), released in January 2023 as voluntary guidance, puts this plainly. Among its characteristics of trustworthy systems, being valid and reliable is “a necessary condition of trustworthiness.”
It is the base the other characteristics rest on. A feature that is impressive but unreliable has not cleared the first bar.
Questions to Ask Before You Commit
If someone proposes an AI feature, a short list of questions tends to separate a considered plan from an enthusiastic one:
- What task is this doing, and how would we do it without AI?
- What does a wrong answer cost the user, and who notices it first?
- Which data does the feature see, and where does it go?
- How will we test it before launch, and how often after?
- What does the product do when the model is unavailable or unsure?
- What does this cost per user per month at ten times current volume?
None of these need a technical background to ask. All of them are difficult to answer convincingly without one.
Design for Human Review
Human review is not a vague safety phrase. Give the reviewer enough context to check the output, a clear way to edit it, and a route to report a failure that the product team can investigate.
The established frameworks ask for oversight you can point to in writing, not oversight you intend to do.
The NIST framework’s Map function expects that “processes for human oversight are defined, assessed, and documented in accordance with organizational policies.”
In the EU, Article 14 of the AI Act (opens in a new tab) requires that systems in its high-risk category be designed so “that they can be effectively overseen by natural persons during the period in which they are in use.”
Not every product falls into that category. The design principle is still a reasonable default well before it becomes a legal one.
The security guidance agrees. The OWASP Top 10 for LLM Applications (opens in a new tab) lists Excessive Agency among its 2025 risks.
Its recommended mitigation is direct: “utilise human-in-the-loop control to require a human to approve high-impact actions before they are taken.”
If a feature can spend money, send messages, or change records on its own, that approval step is part of the build. It is not a later hardening task.
Set Data Rules Before Building
Data access and privacy must be part of the design. Identify what information the feature receives, where it is processed, how long it is retained, and which people or systems may access the result.
OWASP ranks Sensitive Information Disclosure (opens in a new tab) second among its 2025 LLM risks. Its guidance reduces to a rule most teams know but skip under deadline: “limit access to sensitive data based on the principle of least privilege.”
The model is one more system with access to your users’ information, and it should be scoped like one.
The providers publish concrete terms, and they differ enough to matter. Three are worth reading before the design is fixed:
- Training use. OpenAI’s data controls documentation (opens in a new tab) states that “data sent to the OpenAI API is not used to train or improve OpenAI models,” with a separate abuse-monitoring retention window.
- Retention. Anthropic’s retention documentation (opens in a new tab) describes zero data retention as prompts and responses not stored at rest after the response returns. Its own eligibility table marks stateful features as exceptions, so zero retention is not blanket.
- Where inference runs. Geography is configurable and separately priced. Anthropic’s data residency documentation (opens in a new tab) notes US-only inference “is priced at 1.1x the standard rate.”
If the product handles personal data of people in the EU, the design-stage obligation is explicit.
The European Commission’s guidance on data protection by design and by default (opens in a new tab) states that organisations “should ensure that personal data is processed with the highest privacy protection” by default.
That is a decision made before the integration, not after the incident.
Plan the Cost Per User
Do not assume that a hosted AI service is free because the first experiment is inexpensive. Usage, storage, monitoring, retries, review time, and future model changes all affect the operating cost.
AI providers commonly charge for the amount of text processed, so cost grows with use rather than headcount.
The levers are named in the providers’ own pricing documentation (opens in a new tab): model choice, prompt caching, tool-call token overhead, and batching. Anthropic’s Batch API offers “a 50% discount on both input and output tokens” for asynchronous work.
A feature that is uneconomic at full price may be fine when the work does not need to be immediate.
There is a security dimension too. OWASP’s Unbounded Consumption (opens in a new tab) entry describes how “by initiating a high volume of operations, attackers exploit the cost-per-use model of cloud-based AI services.”
This is sometimes called denial of wallet. Rate limits, quotas, and usage monitoring belong in the first release, not the second.
Test With Real Examples First
Build a small test set before calling the feature ready. Use representative examples, include difficult cases, and record the types of mistakes that matter to the people who will use the product.
Both major providers treat this as something you do first, not something you add later.
Anthropic’s guidance on developing empirical evaluations (opens in a new tab) is specific about the shape of a useful set: “be task-specific: design evals that mirror your real-world task distribution. Don’t forget to factor in edge cases!”
OpenAI’s evals guide (opens in a new tab) frames the same practice as understanding how an application performs against expectations. That is what makes a model or prompt change safe to ship.
A useful evaluation does not need to predict every response. It should show whether the feature is helpful for its intended task, where it fails, and when the workflow must return control to a person.
Evaluation also does not stop at launch. Microsoft’s observability guidance (opens in a new tab) describes the lifecycle continuing into production with “quality and safety evaluation of production traffic at a sampled rate.”
Real usage will contain inputs your test set never imagined.
Plan the Fallback
A fallback also needs a practical design. If the model is unavailable, too slow, or uncertain, the product should still explain what the user can do next instead of leaving an empty state or a misleading answer.
Decide in advance what the feature does in three situations: when the model returns nothing usable, when the request times out, and when confidence is low.
Each is a product decision with visible consequences for the user. Each is cheaper to make now than during an incident.
It is also worth deciding how easily you could change model or provider later. Keeping prompts, evaluation sets, and a thin interface between product and model preserves that option.
A Worked Example
To make this concrete, imagine a support team drowning in inbound email. Every message has to be read, categorised, and routed to the right person, and the volume has outgrown the people doing it.
The instinct is to reach for an AI agent that reads each email and replies. Run it through the questions instead.
What is the task, and how would we do it without AI? Routing by keyword and sender already handles the clear cases. The hard part is the ambiguous free-text messages — the shape that suits a model.
What does a wrong answer cost? A misrouted email costs minutes. An automatic reply that invents a refund policy costs far more. So the safe first version suggests a category and a draft; a person still sends.
How will we test it? A few hundred already-resolved emails become the evaluation set, with the messy and unusual ones deliberately included. If the suggested category is right often enough to save reading time, it earns its place.
The feature that ships is narrow: classify and draft, human sends, keyword rules still handle the obvious cases, and everything is logged so the evaluation set keeps growing.
That is a smaller, safer, and cheaper product than the agent the team first imagined — and the one more likely to survive contact with real inboxes.
Deciding What to Build
Using AI to build something and shipping AI inside it are two different decisions. A developer can use AI tools while writing the code and still deliver a product that runs on ordinary software, on AI features, or on both.
For a new product, decide the smallest useful workflow first. Add an AI feature only when it improves that workflow for a defined user and can be tested with evidence that the team can maintain.
The strongest AI product plan is specific about its boundaries. It names the task, the data, the reviewer, the fallback, the evaluation method, and the cost assumptions before the feature becomes a promise.
If you are weighing AI against automation or custom software, bring the decision to the planning conversation early. The right answer may be AI, a rules-based workflow, or no new technology at all.
Get the next post
One email when a new post goes live. Nothing else.
I respect your privacy. Unsubscribe at any time.
Discussion
Comments
No comments yet. Be the first to share your thoughts.